

MEASURE() function—so you can express derived logic on top of existing
semantic definitions with both flexibility and governance.
Calculated fields are expressed as Semantic SQL and pushed down to the Cube
backend for evaluation. The semantic layer compiles them with the rest of the
query—rather than applying them only in the browser—so the same validation,
governance, and warehouse execution path apply as for any other Semantic SQL
analysis.
Using AI to create calculated fields
You can ask the Cube AI agent to create custom calculations in natural language. The agent can add or refine calculated fields from different parts of the product—for example while exploring in Analytics chat or working in Workbooks—so you are not limited to a single entry point when you want a new metric or dimension for the analysis in front of you.Creating calculated fields in UI
You can also build and edit calculated fields directly in the workbook. New fields appear in the Query fields section of the field picker sidebar and belong to the current report. To reuse a dimension in other reports and on dashboards, promote it to a workbook field.Aggregations from existing dimensions
Right-click a dimension column header and choose an aggregation to create a calculated field automatically. Available aggregations depend on the column type:Calculations from existing measures
Open the menu on a measure column header and use the Calculations submenu for derived calculations:% of previous, % change from previous, and Running total require at
least one dimension in the query.
Filtered measures
When working with query Results, pivot so at least one dimension is on columns, then open the header menu on a pivoted measure column and choose Create filtered measure. Cube adds a calculated measure that applies the column’s slice—for example, from Count broken down by Status, you get a measure that only aggregates rows matching that status (such as completed orders only). The option appears only for native measures on pivoted columns, not for calculated fields. The same flow works in Explore when results are pivoted the same way.Bins and value groups
You can also bucket an existing dimension without writing SQL. Open its menu in the field picker sidebar and choose Create bins… on a number dimension, or Group values… on a string or boolean one (grouping a boolean dimension is how you rename itstrue/false values). Time dimensions have granularities
instead, and an already derived field cannot be bucketed again. To count the
time between two time dimensions, see durations.
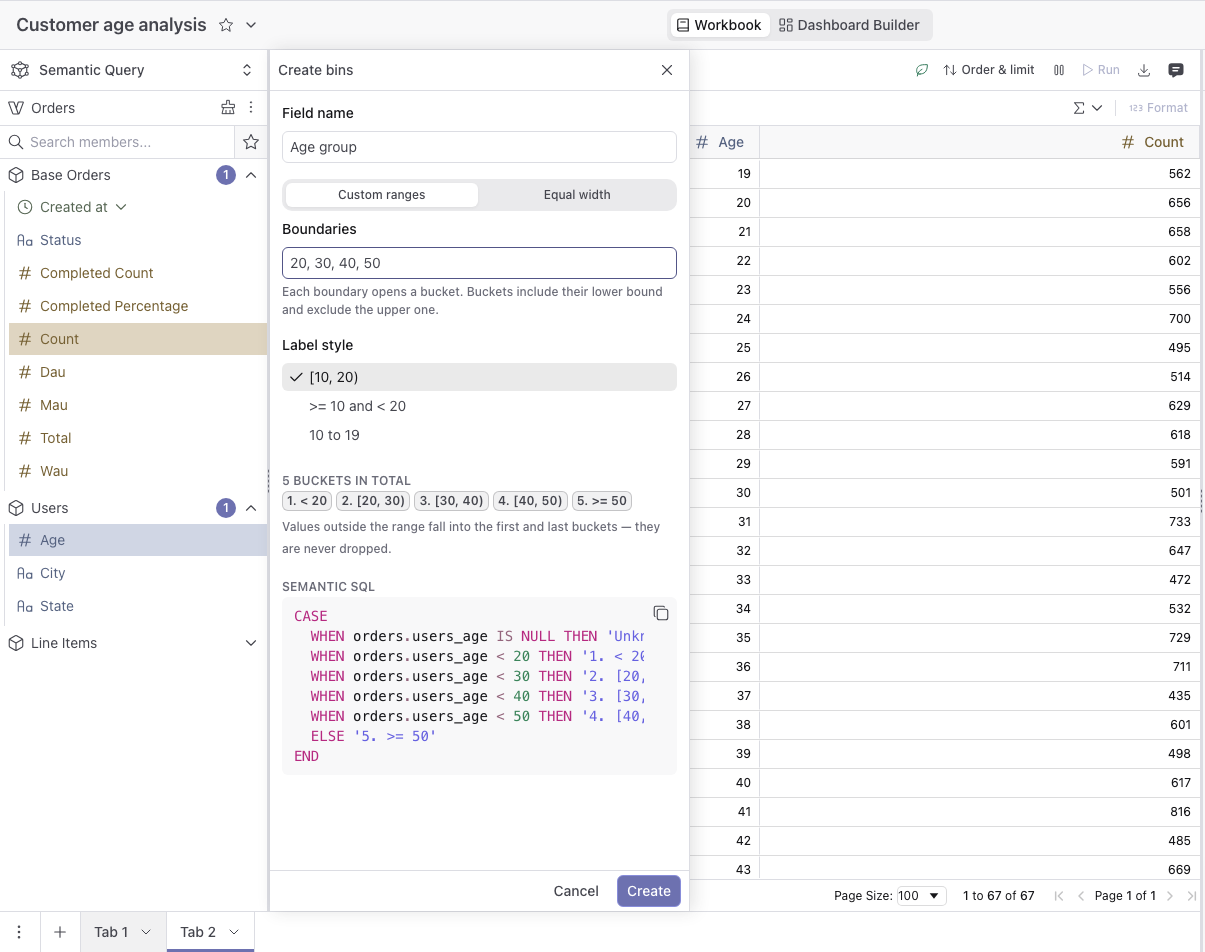
0, 18, 25 yields
< 0, [0, 18), [18, 25), >= 25, and no row is dropped. Label style
renders a bucket as [10, 20), >= 10 and < 20, 10 to 19 (offered only while
every boundary is a whole number), or Custom, which lets you type your own
label for each bucket. Turn off Label empty values separately to fold rows
where the dimension is NULL into the last bucket instead of reporting them
under their own label (Unknown by default).
Value groups collect the dimension’s values into named sets. A group is
defined either by the values you pick or by a rule, chosen with the operator in
front of the search box:
- Search (the default) narrows the list of values. Pick values, name the group, and choose Add group. Select all N matches picks every value the search shows; the list stops at 100 values, so use Contains to catch every match.
- Contains, Starts with, and Ends with define the group by a rule on
the text you type. Is empty takes no text: its rule matches empty strings
(
''), notNULL. The list shows the values the rule matches, without checkboxes. Name the group and choose Add as rule.
NULL values—falls
under Everything else, which defaults to Other; turn off Group remaining
values to have those rows return NULL instead.
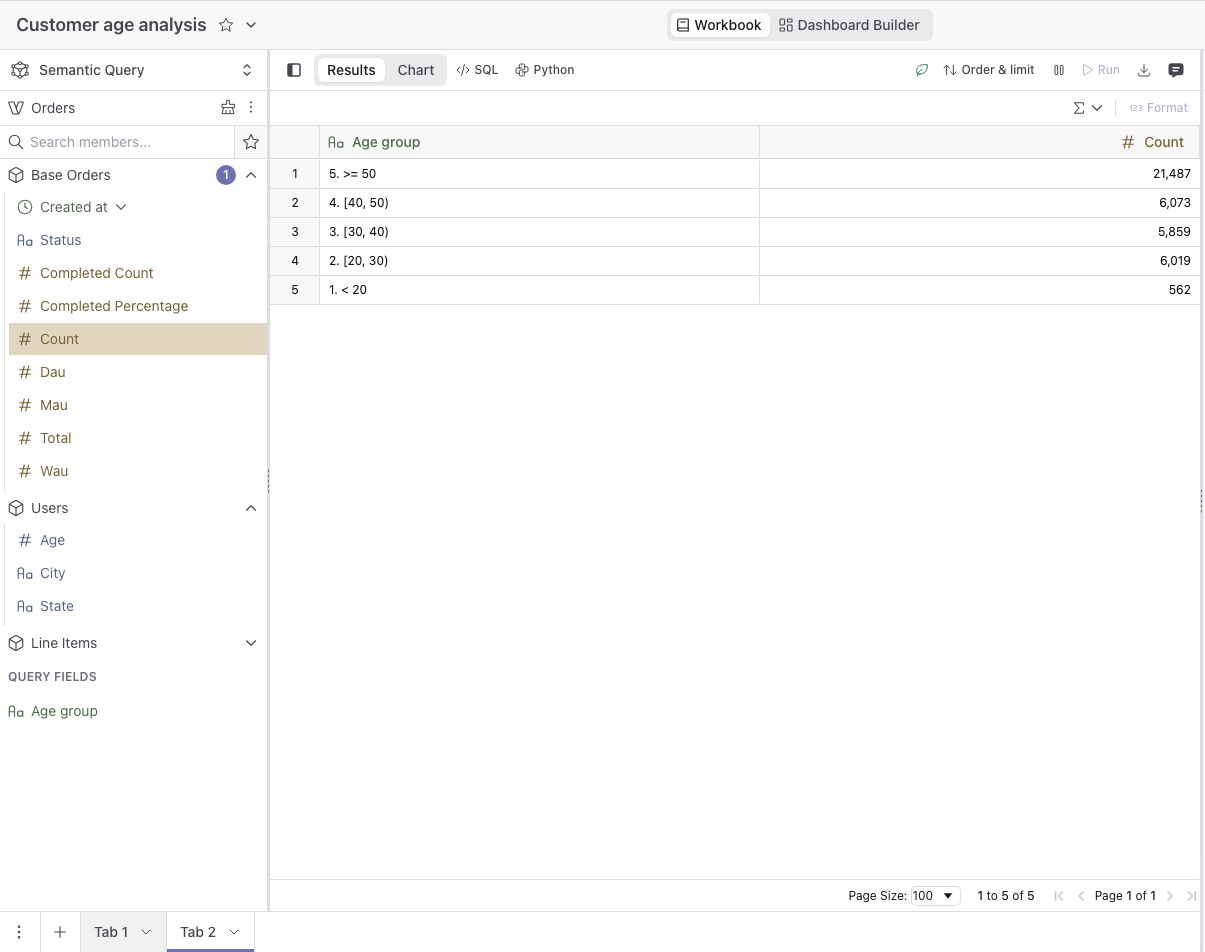
Bucket labels carry their position as a prefix (1., 2., zero-padded past nine
buckets) so that sorting the column sorts it by value rather than alphabetically,
which would put >= 25 before [0, 18). The prefix is visible in results, chart
legends, and axes.
IN, text rules as
ILIKE, and Is empty as = '':
Equal intervals ranges are resolved into boundaries when the field is created, not
recomputed from the data. Values arriving later outside the range join the first
and last buckets instead of extending them.
CASE expression written by hand does
not.
A bucketed field can also be filtered, the same way as a native dimension —
choose Filter from its menu. The value picker offers only the bucket’s own
labels (e.g. Picked and Other), since a bucket can’t return a value it
wasn’t built to produce, and is null / is not null are offered only when
the bucket can actually return NULL. Editing the bucket afterward keeps the
filter’s selection where possible — renaming a label moves the selection with
it — but changing the number of buckets drops a selection that no longer
matches, since the underlying structure changed.
Top N fields
A Top N field keeps the N members of a string dimension with the highest or lowest value of a measure, and groups every other member under one label, such as the 5 biggest customers and an Other row. Choose Top N… in the dimension’s menu in the field picker sidebar, or in its column header menu in the results. The panel has these settings:- Show — Top or Bottom, and N. N starts at 10.
- Ranked by — the measure to rank by. It starts on the first measure the report shows.
- Ranked within — other dimensions of the report. Leave it on Whole report to rank across the whole report, or pick dimensions to keep N members in each group.
- Group remaining values as — the label of the rest, Other by default.
Durations between dates
You can count the time between two time dimensions of a semantic view without writing SQL, for example the days fromcreated_at to shipped_at. Open the
menu of the start date in the field picker sidebar and choose Create
duration…. The action is offered on a time dimension of the data model when
the semantic view has at least one other time dimension.
In the Create duration panel, the time dimension you opened the menu on is
the Start date. Select the End date from the other time dimensions of
the semantic view, and choose a Unit: Days, Hours, Weeks or
Months. The Field name follows your picks, for example
Created At to Shipped At (days), until you type your own. Choose Create
to add the field to Query fields.
The panel previews the Semantic SQL it generates:
1 day, and from 00:01 to
23:59 the same day is 0 days. Both dates are converted to the query time zone
first. When the end date is earlier than the start date, the value is negative,
and when either date is empty, the value is empty.
The generated field is a regular calculated field, with no Edit duration…
action: to switch the unit, edit its SQL expression.
Like any calculated dimension, you can promote it to a workbook field.
Promoting to a workbook field
A query field belongs to one report. A workbook field belongs to the workbook: it is listed under Workbook fields in the field picker sidebar of every report on the same semantic view, and dashboard filters and field switchers can target it. To promote a calculated dimension, choose Promote to workbook field from its column header menu in the results or from its menu in the sidebar. In the Save calculated field dialog, enter a Name and, optionally, a Title, Description and Format, then choose Save. The field stays a dimension, and Value type is prefilled from its SQL. Only dimensions can be promoted. Calculated measures stay query fields.Promoting to the data model
A workbook field exists only in its workbook. To add it to the data model, choose Promote to data model from its menu in the field picker sidebar. Cube opens the data model page of the deployment, with a prompt for the Semantic Model Agent in the chat input. The prompt describes the field: its name, title, description, semantic view, kind, type, format and Semantic SQL expression. If the field is built on other workbook fields, the prompt also includes their expressions. It asks the agent to:- Find the cubes behind the semantic view members that the expression uses.
- Stop if the data model already has an equivalent member, and name it.
- Otherwise, add the member to the cube and include it in the semantic view.
- Review the change.
- Commit the change to a new branch and open a pull request. If the repository cannot open one, the agent leaves the change on the development branch.
- You have the Developer role or a role above it.
- AI features are available for your account, and the deployment has an agent.
- You can edit the data model, on the main branch or on development branches.